
klodmem: Full-Text Search for Claude Code's Memory and History
Claude Code writes memory files as it works: little markdown notes about your
preferences, your project’s quirks, decisions you’ve made. Handy, except for
one thing: the only way back to them is MEMORY.md, a one-line index per
memory, matched by exact keyword. Ask about “port conflicts” when the note
actually says “docker-compose mapping” and you get nothing.
And every project’s memories live in their own silo: what Claude learned about you in one repo is invisible in the next.
I got tired of memories I knew existed but couldn’t find. So I built klodmem. Check it out on GitHub.
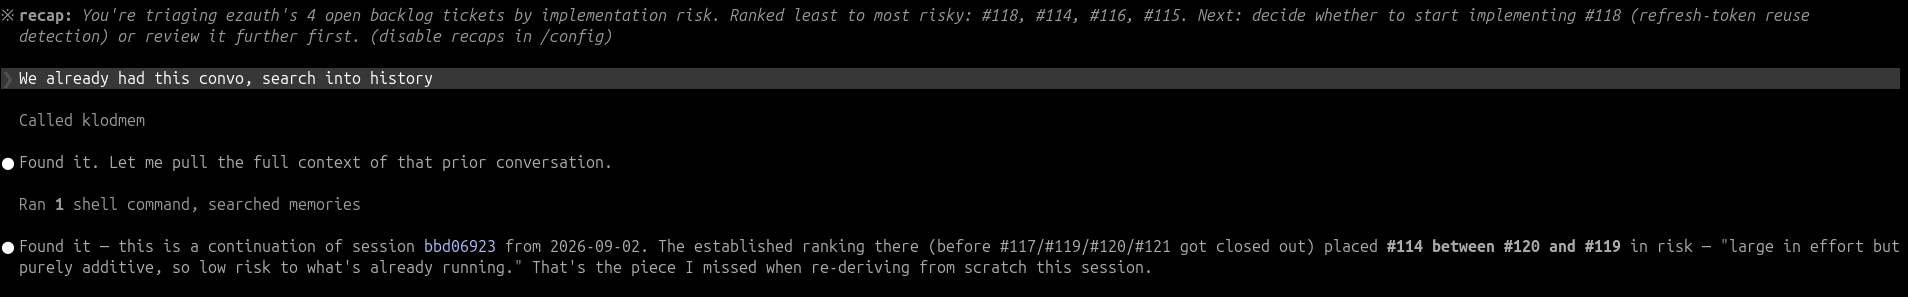
Ask in plain language, get the memory back.
Quick start, if you want it running now:
go install github.com/josuebrunel/klodmem/cmd/klodmem@latest
claude mcp add --scope user klodmem -- klodmem
# restart Claude Code
claude mcp get klodmem
Then just ask, in a session: “search my memories for docker-compose port conflicts” or “have I debugged this error before?”
The Two Search Tools
klodmem is an MCP server. It doesn’t touch how Claude Code writes memories, it just makes what’s already there findable with two tools:
search_memoryindexes every memory file’s actual content, not just itsMEMORY.mdindex line, across every project on the machine. Filter by project, by type (user/feedback/project/reference), or just search everything.search_historydoes the same over raw session transcripts, so a discussion that never made it into a memory file is still findable. Past you debugged this exact error in a different repo six weeks ago? Now that’s searchable instead of gone.
Both answer the same shape of question: have I dealt with this before?
How the Index Works
The searchable index is a side effect of your files, not a second source of truth:
- Markdown stays the source of truth. klodmem only reads your memory files and transcripts and indexes them into a local SQLite database.
- Live updates. File watchers keep the index current while a session is open, so a memory written five minutes ago is already searchable.
- Incremental history scans. klodmem tracks a byte offset per transcript file and only reads what’s new, so re-scanning a long-running project doesn’t mean re-reading its entire history every time.
The Stack (Briefly)
Go, SQLite with FTS5 for the actual search (porter-stemmed full-text tables,
one for memories and one for history), fsnotify for the file watching, and
the official MCP Go SDK for the server itself. The SQLite driver is
modernc.org/sqlite, pure Go, no cgo, so go install is genuinely the
whole install story, no C toolchain required. It’s the same “boring on
purpose” reasoning I wrote about in
My SaaS Tech Stack: fewer
moving parts, one static binary, nothing to babysit.
What Works, What Doesn’t
What works:
- Searching across every project at once, which is the whole point: memories and conversations stop being trapped in whatever directory you happened to be in when Claude learned them
- Live indexing, so it’s not a “run this batch job every so often” tool
- Zero-dependency install: one
go install, oneclaude mcp add, done - The index is disposable. Delete the SQLite file, klodmem rebuilds it from your markdown and transcripts on next start
What doesn’t (yet):
- It’s keyword search, not semantic search. FTS5 with porter stemming catches “debugging” when you search “debug,” but it won’t catch a pure paraphrase with no shared words. I thought about embeddings, and passed. Vector search means an embedding model, a vector store, and either an API key or something heavy running locally, all to rescue a memory I can usually reach by retyping the search with a synonym. Keyword search is the boring choice, and boring is what keeps this tool one static binary, no keys, no network calls.
- History indexing only covers authored user and assistant text: tool input/output, thinking blocks, images, and subagent transcripts aren’t indexed, so part of a conversation can still be invisible
- The index is local to one machine. If you work across a laptop and a desktop, each one builds and searches its own copy
The Payoff
I no longer lose memories to the wrong keyword. If Claude wrote it down, or
even just talked about it in a past session, search_memory or
search_history finds it, regardless of which project I was in when it
happened. Small tool, but it closes a gap that got more annoying the more
projects I had open.
klodmem is open source. View on GitHub.